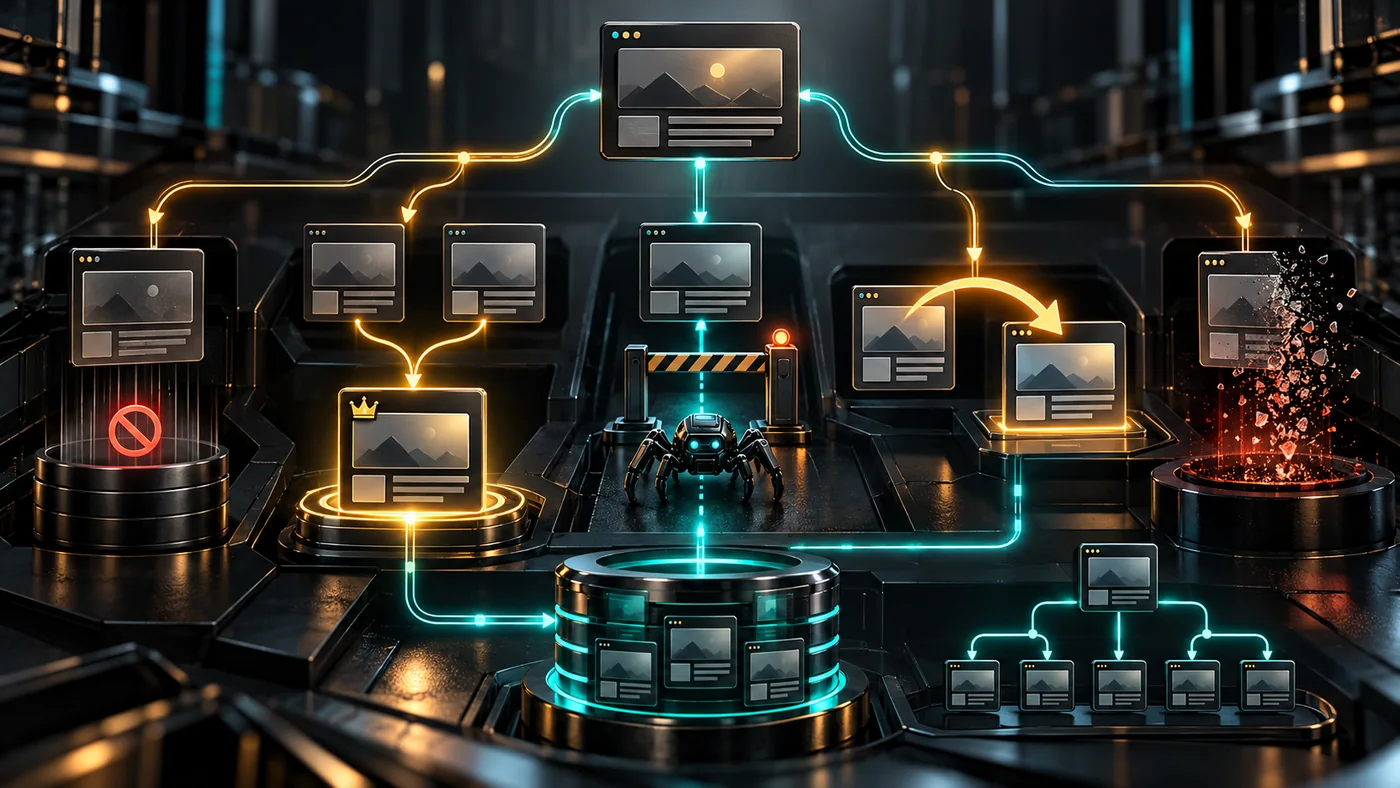
Use noindex when a crawlable page should stay out of search, canonical when duplicate URLs should consolidate into a preferred version, robots.txt when you need to control crawling, and a redirect when content has moved. Nofollow qualifies links; it is not the default solution for links to noindex pages or a reliable crawl-budget switch.
THE SHORT VERSION
Match the directive to the problem
Noindex, nofollow, robots.txt or canonical?
| Desired outcome | Primary control | Keep crawlable? | Typical example |
|---|---|---|---|
| Page may serve users but should not appear in search | noindex |
Yes, until crawlers process the rule | Internal search results or a thin utility page |
| Several URLs contain substantially the same content | rel="canonical" |
Yes | Filtered or parameterized product URLs |
| Old URL has a clear replacement | 301 or 308 redirect | The old URL must remain reachable enough to redirect | Changed slug or consolidated article |
| Page is permanently gone and has no relevant replacement | 404 or 410 | Return the status when requested | Expired content with no substitute |
| Reduce crawler access to a path | robots.txt |
No for compliant crawlers | Faceted crawl spaces or generated files |
| Qualify a paid, UGC or untrusted outbound link | sponsored, ugc or nofollow |
Not applicable | Affiliate link, forum link or untrusted source |
| Protect private or confidential content | Authentication and authorization | No public access | Account, medical or client data |
Noindex: remove a page from search, not from the website
A noindex rule tells supporting search engines not to show the page in search results. For an HTML document, place it in the page head:
<meta name="robots" content="noindex, follow">For a PDF, image or another non-HTML resource, return the rule in the HTTP response:
X-Robots-Tag: noindexGoogle must crawl the URL to discover either rule. If the URL is blocked in robots.txt, Google cannot read the page-level noindex; the URL may still appear without a snippet when Google learns about it from links. Google also does not support a noindex rule inside robots.txt.[1][2]
Should a noindex page use follow or nofollow?
For most crawlable utility pages, noindex, follow is a reasonable explicit configuration, and plain noindex is usually enough because follow is the default. The links can still help crawlers discover useful destinations while the page itself stays out of search.
Do not assume this relationship lasts forever. Google has explained that after a URL remains noindex for a long period, it may eventually be crawled less often and its links may no longer function like links from a regularly indexed page. Important pages should therefore receive direct internal links from indexable navigation or content, not depend on a noindex page as their only route.
Noindex is not access control
A noindex page remains publicly accessible to anyone with the URL. It can be shared, linked, logged or viewed by crawlers that ignore the directive. Use a login, permissions, network restriction or removal for confidential information.
Nofollow: qualify a link, not an internal architecture strategy
The rel="nofollow" attribute applies to a link. It does not noindex the source or destination page:
<a href="https://example.com/page" rel="nofollow">Example</a>Google treats nofollow, ugc and sponsored as link qualifications and generally as hints for crawling and ranking—not as guaranteed barriers.[3] Use:
rel="sponsored"for advertising, sponsorship and paid placements;rel="ugc"for user-generated links such as forums or comments;rel="nofollow"when the other values do not fit and you do not want to associate the site with the destination.
Do not add nofollow to every internal link that points to a noindex page merely to “save crawl budget.” It can weaken discovery and does not guarantee that Google will not crawl the URL through another link, a sitemap or an external source. Fix crawl traps at their source, remove unnecessary links, simplify faceted navigation or use robots.txt for a genuine crawl-control problem.
Robots.txt: crawling control with indexing limitations
A robots.txt rule asks compliant crawlers not to fetch matching paths:
User-agent: *
Disallow: /internal-search/
Robots.txt is useful for managing crawler traffic and large spaces that should not be fetched. It is not a reliable method for keeping a known URL out of search. Google may index a blocked URL based on links and show only the URL or limited information.[2]
The robots.txt + noindex conflict
This is the common mistake:
- The page contains
noindex. - The same URL is disallowed in robots.txt.
- Google cannot crawl the page and therefore cannot see the noindex.
To remove an already indexed page, allow crawling, serve noindex, request recrawling when appropriate and wait until the index updates. Only then consider crawl restrictions if they are still necessary—while understanding that future verification of the noindex rule becomes harder.
Canonical: consolidate duplicates, not remove unique pages
A canonical link identifies the preferred representative of duplicate or very similar pages:
<link rel="canonical" href="https://example.com/preferred-page/">Google treats canonical annotations as signals, not directives. Redirects and canonicals are strong signals; sitemap inclusion is weaker. Signals that agree improve clarity.[4]
Canonical versus noindex
- Use canonical when the content should remain represented in search through another equivalent URL.
- Use noindex when this content should not appear in search at all.
- Avoid combining noindex and canonical on the same URL as a routine strategy. The signals express different intentions and Google may choose an outcome you did not expect.
Canonical is also not a substitute for a redirect when the old URL should disappear for users. If there is one permanent replacement, redirecting is clearer.
Redirect, 404 or 410: when the page itself is no longer needed
Use a permanent redirect when there is a true replacement
Use a 301 or 308 when a page moved, a duplicate was consolidated or an old article was merged into a new resource that satisfies the same intent. Update internal links and the sitemap to point directly to the destination.
Use 404 or 410 when there is no relevant replacement
Do not redirect every deleted URL to the homepage. That creates a poor user experience and may be treated as a soft 404. A normal 404 is valid; a 410 states explicitly that the resource is gone. Remove the URL from internal links and sitemaps.
Use authentication for private content
Login pages, customer documents and staging environments need real access control. Search directives are publishing hints, not security boundaries.
Sitemaps and internal links: make your intent consistent
An XML sitemap should generally contain the canonical URLs you want indexed. Remove noindex, redirected, error and noncanonical URLs. A sitemap does not force indexing, but including unwanted URLs sends a conflicting signal.
Internal links should normally point to final, canonical, indexable destinations. Links to necessary noindex pages—login, cart or filters—can remain normal when users need them. The architectural question is whether these links create an unlimited crawl space, not whether every noindex destination must be nofollowed.
Practical decision scenarios
| Scenario | Recommended action | Avoid |
|---|---|---|
| Internal search-results pages | Noindex; exclude from sitemap; control infinite combinations if needed | Indexing thousands of thin query pages |
| Product filters with duplicate content | Canonical to the clean category when genuinely equivalent; manage crawl patterns separately | Canonicalizing filters that serve unique search intent |
| Expired product with a direct successor | 301 to the successor if it truly replaces the product | Redirecting to an unrelated category or homepage |
| Expired product with no replacement | Helpful unavailable page, 404/410 when permanently removed, and updated internal links | Leaving it in the sitemap |
| Campaign landing page after the campaign | Keep and update, redirect to a relevant evergreen replacement, or remove based on continuing value | Automatic homepage redirect |
| PDF that should not rank | X-Robots-Tag: noindex |
Trying to add an HTML meta tag inside the PDF |
| Staging site | Authentication, IP restriction or private network; noindex as a secondary safeguard | Relying on robots.txt alone |
| Paid outbound link | rel="sponsored" |
Using canonical or noindex to qualify the link |
A 15-minute directive audit
- Export URLs with status, robots directives, canonical, sitemap membership and inlinks.
- Find URLs that are both noindex and blocked by robots.txt.
- Find noindex, redirected, error or noncanonical URLs in XML sitemaps.
- Find canonicals that redirect, return errors or point to noindex pages.
- Check whether important indexable pages rely on noindex pages for discovery.
- Review internal nofollow usage and remove blanket crawl-budget patterns.
- Inspect representative URLs in Search Console to compare user-declared and Google-selected canonical.
- Recrawl after changes and record the date; index changes require another Google crawl.
Common questions
Will noindex preserve crawl budget?
Not immediately. Google must crawl the page to see the rule, and may revisit it. Noindex is an indexing control. Large crawl inefficiencies require architecture, link, parameter and robots.txt analysis.
Should links to noindex pages be nofollowed?
Not by default. Keep useful internal links usable and crawlable. Use nofollow to qualify a relationship, not as a blanket patch for noindex pages.
Can a robots.txt-blocked page appear in Google?
Yes. Google may know the URL from links and list it without crawling the content. Use crawlable noindex for removal from search.
Does canonical guarantee Google will select my preferred URL?
No. It is a strong signal. Improve consistency with redirects, internal links, sitemaps, matching content and correct hreflang where relevant.
Official sources
Checked October 11, 2026.