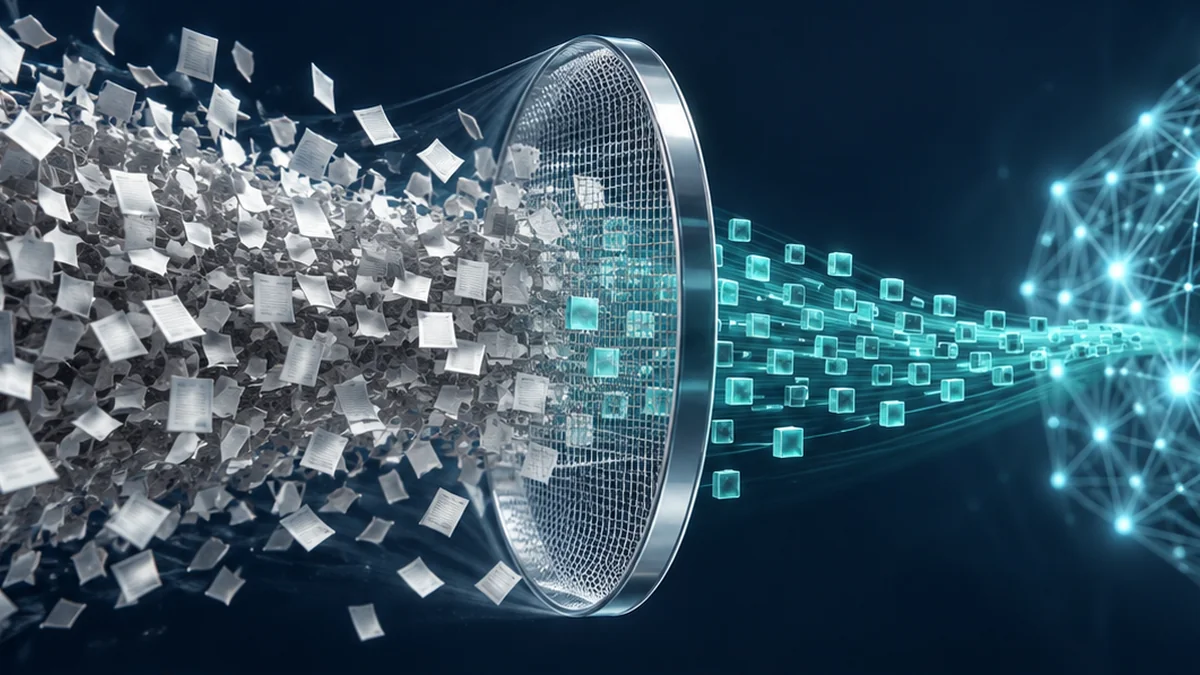
Short answer: The original GPT-3 paper reports 45TB of compressed Common Crawl plaintext before filtering and 570GB after filtering for that source. These are not two separate training totals. GPT-3 also used WebText2, Books1, Books2 and Wikipedia in a weighted mixture; the paper says its models were trained for 300 billion tokens.
Here is what the figures mean, and what they do not tell us.
45TB vs 570GB: before and after filtering
Brown et al. describe 41 Common Crawl monthly shards from 2016–2019, totaling 45TB of compressed plaintext before filtering and 570GB after filtering. This is the filtered Common Crawl component, not a claim that the complete GPT-3 training mixture occupied exactly 570GB. The paper also lists WebText2, Books1, Books2 and Wikipedia; dataset sampling was weighted rather than proportional to raw size. See Language Models are Few-Shot Learners, section 2.2 and table 2.2.
The Intricacies of Parameters:
The largest GPT-3 model in the original paper has 175 billion parameters. Parameters describe the model architecture, not the size of the training dataset. The paper says the trained models saw 300 billion tokens; tokens, filtered source bytes and parameter counts measure different things and should not be added together.
Can training cost be calculated from dataset size?
No reliable dollar cost follows directly from 45TB, 570GB, 300 billion tokens or parameter count. Hardware, utilization, training implementation and accounting assumptions matter. Older cost estimates for reproducing GPT-3 are third-party estimates, not a measured OpenAI bill in the original paper. This guide therefore avoids presenting a speculative dollar figure as fact.
Questions & Answers about GPT-3
How much data was used to train GPT-3?
The paper reports 45TB of compressed Common Crawl plaintext before filtering and 570GB after filtering for that component. Other sources were also part of the mixture; the models trained for 300 billion tokens.
How many parameters did GPT-3 have?
The largest GPT-3 model reported in the original paper had 175 billion parameters. This is model size, not dataset size.
Is 570GB the full GPT-3 training corpus?
No. It is the filtered Common Crawl component reported by the paper, which also lists WebText2, Books1, Books2 and Wikipedia.
What the original GPT-3 paper actually supports
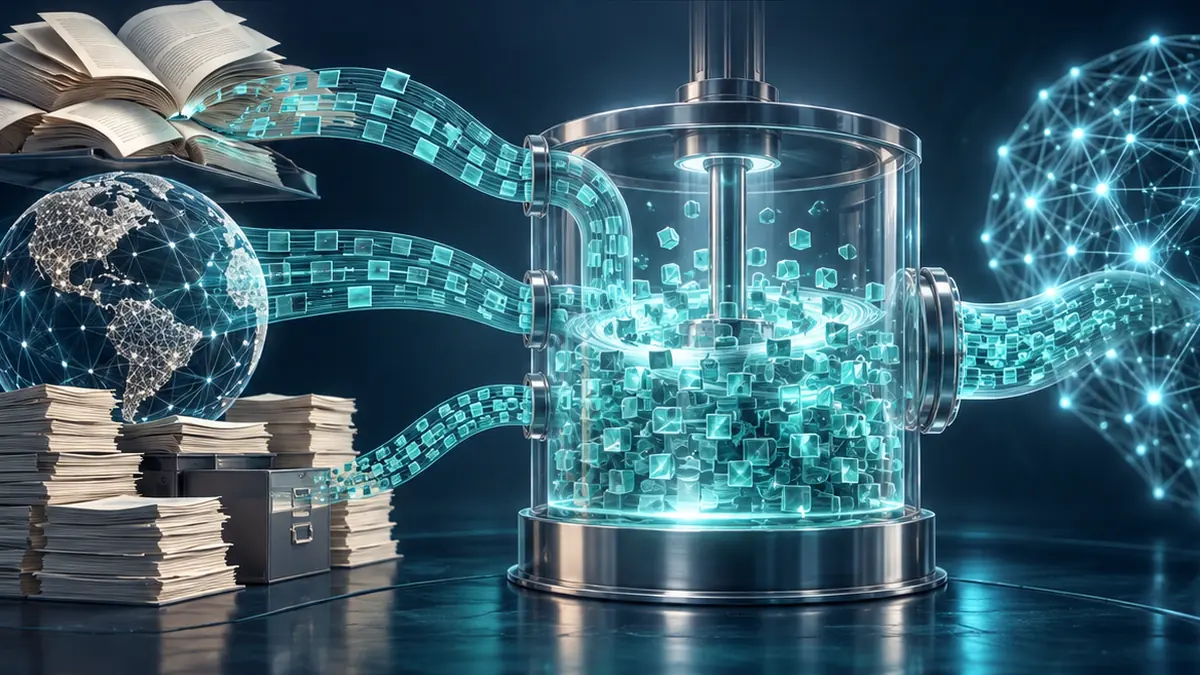
The useful distinction is source collection → filtering → weighted training mixture. Quoting the 45TB input as “the training data size” collapses those stages and misleads readers; 570GB alone omits the other listed sources. For the exact dataset mixture and methods, read Brown et al. (2020). Figures here describe the original GPT-3 paper, not the undisclosed training data of later models. Reviewed September 2026.