GPT-3 is OpenAI’s 2020 family of autoregressive language models, best known for its 175-billion-parameter version. It generates text by predicting the next token from the preceding text. Its important contribution was showing how a large model could perform different tasks from instructions and examples in a prompt, without being retrained for each task. GPT-3 is not ChatGPT, and its original API models are retired.
This guide explains the original research model: its architecture, training, capabilities and limitations. In 2026, its value is as a foundation for understanding language models—not as a recommendation for a new deployment.
What is GPT-3?
GPT stands for Generative Pre-trained Transformer. “Generative” means it produces text; “pre-trained” means it learns from a large text collection before being used for a particular task; and “Transformer” names the neural-network architecture. A token is a piece of text, which may be a word, part of a word or punctuation.
OpenAI described GPT-3 in Language Models are Few-Shot Learners, by Brown et al. (2020). Rather than building a separate model for every language task, the researchers tested one language model under zero-shot, one-shot and few-shot prompting conditions.
GPT-3 architecture and parameters
GPT-3 uses a decoder-only, autoregressive Transformer: it processes the preceding tokens and predicts what comes next, then repeats that process to build a response. Attention lets it use relationships between tokens inside its context window. This is not the same as looking up an answer in a database or searching the live web.
The architecture follows GPT-2, with alternating dense and locally banded sparse attention patterns. The largest GPT-3 configuration has 175 billion parameters, 96 layers and 96 attention heads. Parameters are learned numerical weights, not documents, facts or a direct measure of answer quality. All eight research configurations used a 2,048-token context window. These specifications come from section 2.1 and Table 2.1 of the paper; they should not be assigned to GPT-3.5 or later models.
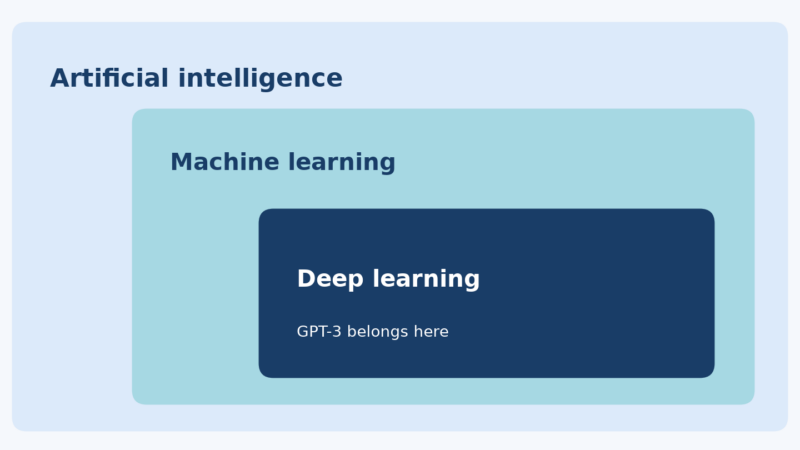
How many GPT-3 model sizes were there?
The paper reports eight sizes: 125M, 350M, 760M, 1.3B, 2.7B, 6.7B, 13B and 175B parameters. Here, M means million and B means billion. They are separate model configurations, not task-specific “partitions” that users create. Splitting a model across GPUs is model parallelism, a different concept.
Compared with GPT-2, GPT-3’s main historical advance was the much larger scale and the systematic demonstration of in-context learning across tasks. It did not introduce the Transformer, and being larger did not make it reliably factual.
How was GPT-3 trained?
During pre-training, a language model adjusts its weights to become better at predicting text. GPT-3’s training mixture combined filtered Common Crawl, WebText2, Books1, Books2 and Wikipedia, with sources sampled at different rates rather than simply in proportion to their size.
The paper reports 300 billion training tokens. It also reports 45TB of compressed Common Crawl plaintext before filtering and 570GB after filtering. Those byte figures describe one source at two processing stages—not two separate training totals, and not the size of the complete mixture. Tokens, bytes and parameters measure different things.
For the fuller explanation of collection, filtering and weighted sampling, see how much data was used to train GPT-3. The primary reference is section 2.2 and Table 2.2 of the original paper.
Few-shot prompting is not fine-tuning
- Zero-shot: describe the task without supplying worked examples.
- One-shot: supply one example in the prompt.
- Few-shot: supply several examples in the prompt.
- Fine-tuning: carry out additional training that changes the model’s weights.
In the paper’s task evaluations, GPT-3 used instructions and examples in its context without gradient updates or task-specific fine-tuning. The examples temporarily guide the output; they do not permanently retrain the model. That distinction still matters when deciding whether a problem needs a clearer prompt, better reference material or additional training.
What could GPT-3 do—and where did it struggle?
GPT-3 could generate and complete text, answer questions, classify text and translate between languages. Its paper also explored tasks such as arithmetic, word manipulation and writing news-style articles. Results varied substantially by task and prompting setup.
Drafting, rewriting and summarizing are possible ways to prompt a text model, but they are not guarantees of faithful output. The GPT-3 paper documents weaknesses in text coherence, sentence comparisons and reading comprehension. Likewise, producing code-like text does not establish reliable software-engineering ability: generated code needs testing. GPT-3 itself was a text model, not an image generator or a text-to-speech system.
- Fluency is not accuracy. A convincing continuation can contain false claims, weak reasoning or inconsistencies.
- Context is limited. The original 2,048-token window constrained how much instruction, reference text and output could fit together.
- Data brings risks. The paper discusses bias, memorization and potential misuse. Filtering does not guarantee that inaccurate, sensitive or biased material is absent.
- Evaluation can be contaminated. The researchers disclosed overlaps between some training and benchmark data after a filtering bug. A published score needs its methodological context.
GPT-3 translation performance: what the paper actually measured
The original research provides numerical translation results, so there is no need to infer scores from an unscaled graphic. The table below transcribes the GPT-3 rows of Brown et al., Table 3.4.
| Translation direction | Test set | Zero-shot | One-shot | Few-shot |
|---|---|---|---|---|
| English → French | WMT14 | 25.2 | 28.3 | 32.6 |
| French → English | WMT14 | 21.2 | 33.7 | 39.2 |
| English → German | WMT16 | 24.6 | 26.2 | 29.7 |
| German → English | WMT16 | 27.2 | 30.4 | 40.6 |
| English → Romanian | WMT16 | 14.1 | 20.6 | 21.0 |
| Romanian → English | WMT16 | 19.9 | 38.6 | 39.5 |
Method: Table 3.4 uses multi-bleu.perl with XLM’s tokenization. The paper reports SacreBLEU results separately in Appendix H; those numbers should not be mixed with this table. The translation experiments used one or 64 paired examples in the one-shot and few-shot settings, respectively.
What this shows: examples in the prompt improved the reported scores in these experiments, and translation direction mattered. BLEU measures overlap with reference translations, not the percentage of sentences translated correctly. These are historical research results—not tests conducted by this site, a comparison with current models or proof that GPT-3 was best for every language.
GPT-3 vs GPT-3.5 vs ChatGPT: different names, different things
A model family, an assistant application and a way of distributing model weights are not interchangeable categories. Keeping them separate makes comparisons more useful.
| Name or category | What it means | What not to assume |
|---|---|---|
| GPT-3 | The 2020 language-model family discussed here. | Its 175B parameter count and 2,048-token context are not specifications for other GPT generations. |
| GPT-3.5 / GPT-3.5 Turbo | A later model generation; OpenAI describes GPT-3.5 Turbo as optimized for chat and labels it a legacy model. | It is not another name for the original GPT-3, and its name does not establish its parameter count. |
| ChatGPT | OpenAI’s user-facing assistant application, powered by models and product features. | The product name does not identify one fixed underlying model or an API model ID. |
| Open-weight models, such as GPT-Neo | Models with downloadable weights, subject to their individual licenses and hardware needs. | They are not downloadable GPT-3, and open weights alone do not establish quality, privacy or operating cost. |
For the model/product distinction, see OpenAI’s GPT-3.5 Turbo documentation, API model catalog and Model Spec. EleutherAI’s GPT-Neo model card documents a separate downloadable model. Publishing a research paper is not the same as releasing trained weights or an open-source implementation.
The same distinction applies to a marketing application such as Jasper: evaluate the application’s workflow and controls separately from any underlying language model. For practical assistant workflows rather than GPT-3 history, continue to ChatGPT for SEO.
Can you still use GPT-3? What happened to the API?
The original GPT-3 API models are retired. OpenAI’s deprecation record, under “2023-07-06: GPT and embeddings,” lists ada, babbage, curie and davinci with a shutdown date of January 4, 2024. Old tutorials using those model IDs are not current setup instructions.
The retirement of those IDs does not mean that every later completion or chat model was retired on that date. Nor should the replacement models listed in a historical announcement be treated as today’s default recommendation. For a new application, check the current API model catalog and the deprecation entry for the exact model ID you plan to use.
GPT-3 was not released as an open-weight download. Its historical API access did not give developers a local copy of the original weights. If local execution is essential, investigate a genuinely downloadable model and check its license, memory requirements and data-handling setup instead.
What GPT-3 still teaches us about choosing models
The useful lesson is not “pick the largest parameter count.” It is to evaluate a named model in the conditions in which you will actually use it:
- Define the task. Translation, extracting structured information and drafting an article need different checks. Include the languages and difficult cases your users encounter.
- Control the comparison. Use the same source material, instructions and scoring criteria. Record the exact model version, examples supplied and any retrieval or tools involved.
- Separate the model from the system. Search, reference documents and application safeguards can change results. Compare the complete workflow when that is what users will experience.
- Check practical constraints. Confirm availability, context limits, cost, latency, licensing and data handling in current documentation. Do not reuse GPT-3’s historical specifications as a shortcut.
- Review failures before publishing. Verify facts and citations, test generated code and use human review where mistakes matter.
For SEO work, use AI to assist research organization and drafting—not to replace source checks or publish unverified claims. Our ChatGPT prompt examples provide a practical starting point; the output still needs editorial judgment.
Sources and scope
- Brown et al. (2020), Language Models are Few-Shot Learners: architecture and model sizes in section 2.1/Table 2.1; training in section 2.2/Table 2.2; translation in section 3.3/Table 3.4; limitations and broader impacts in sections 5–6.
- OpenAI API deprecations: retirement dates for named API models.
- OpenAI GPT-3.5 Turbo documentation and model catalog: terminology and current model-selection references, not a benchmark against GPT-3.
- OpenAI Model Spec: context on intended assistant behavior and OpenAI products; intended behavior is not proof that every response meets it.
- EleutherAI GPT-Neo 1.3B model card: a historical example of a separate model with downloadable weights.
Sources checked October 15, 2026. Numerical performance results above are transcribed from the original GPT-3 paper; they are not new tests by Seo4Starters. This guide covers the historical GPT-3 model, not unpublished specifications or predictions about future models.